
Data schema
Attribution collects a number of data points that can be exported. Data scientists, analysts and developers can use the schema below to design custom reports on top of this data.
The export holds the same data, in the same form, that your dashboard uses to build every report. It is raw, as collected, with no attribution model applied.
Modeled data cannot be exported, because the model depends on what you select on the dashboard at the time: the filters, the date range, the model and the attribution type. The export contains no pre-built reports either.
The diagram below shows how the raw data is laid out. Some tables hold normalised data, so the same information can appear in two tables in different forms: the params table stores the URL parameters parsed out of the events.uri column.
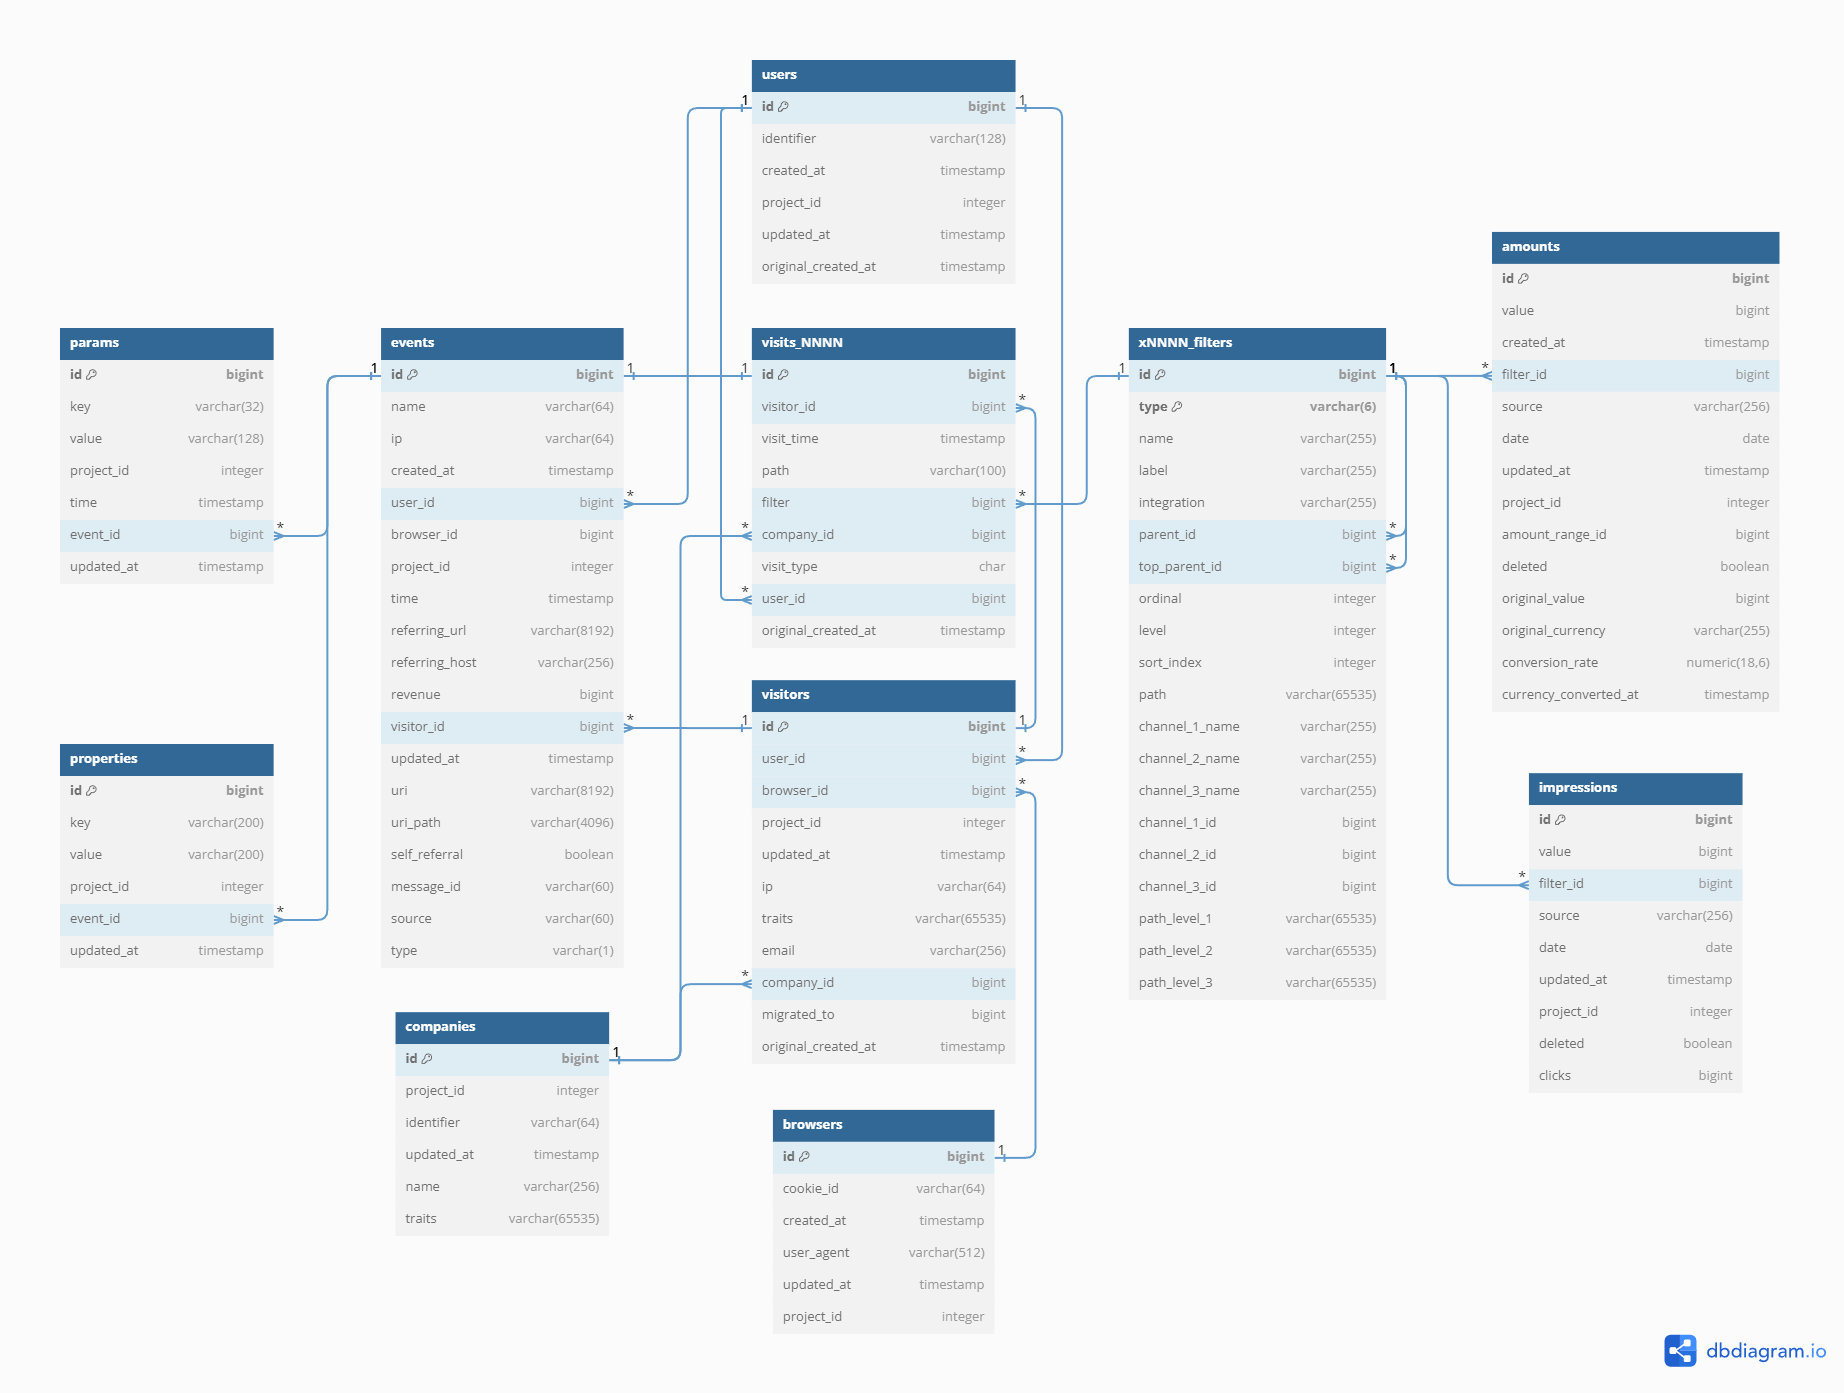
Events
The events table contains every event and pageview from the track() and page() calls, and every event sent server-side. Event properties are not stored here but in the properties table.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID of the pageview or track event. Primary key, referenced from other tables. |
name | VARCHAR | The event name. Pageviews are Loaded a Page or Viewed * Page, depending on how you call page(). |
ip | VARCHAR | IP address of visitor. |
created_at | TIMESTAMP | When the event was written to the Attribution database. |
user_id | BIGINT | References users.id. This is the internal ID generated by Attribution, not the userId you pass when tracking. |
browser_id | BIGINT | References browsers.id. |
project_id | BIGINT | Internal ID of your project. |
time | TIMESTAMP | When the event happened. |
referring_url | VARCHAR | HTTP Referer URL of the pageview. |
referring_host | VARCHAR | Hostname part of referring_url. |
revenue | BIGINT | Revenue property value in cents. |
visitor_id | BIGINT | Internal ID of visitor. References visitors.id. |
updated_at | TIMESTAMP | When the event was last updated. |
uri | VARCHAR | Pageview URL at capture time. |
uri_path | VARCHAR | URL path of uri. |
self_referral | BOOLEAN | TRUE if referring_host matches uri hostname, FALSE otherwise. |
message_id | VARCHAR | Unique event ID generated by the library that sent the event. |
source | VARCHAR | Name of the source the event was captured from. |
type | VARCHAR | p for pageviews from page(), t for events from track(). |
Visits (touchpoints)
The visits table is named after our internal ID for your project: if that ID is 1234, the table is visits_1234. It contains everything you see as Visits on the dashboard.
Visits are touchpoints: a visit is the first pageview of a session; see Visits and visitors. We do not call them sessions, because a session is the whole group of pageviews and events, while the visit is only the first pageview, the one that carries the source of the session in its URL parameters, its referrer or both. The source of a visit, and of the session that follows it, is called a filter in Attribution.
Heads up!This table holds the most valuable information for building custom reports on Attribution's data.
Unlike most other tables, this one is NOT exported incrementally: drop the existing visits table and load it in full with every export. Visits depend on filters, and filters are added, changed and removed all the time, by integrations and by your marketing team, so the visits table is rebuilt from the events and filters tables on every run.
In other words, visits are the result of applying filters to events: if a filter has the rule "URL parameter
utm_sourceispartner", every pageview withutm_source=partnerin its URL is written to the visits table.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | References events.id. Unique within visits, usable as the primary key. |
visitor_id | BIGINT | References events.visitor_id and visitors.id. |
visit_time | TIMESTAMP | References events.time. |
filter | BIGINT | References xNNNN_filters.id where xNNNN_filters.type is filter. Replace NNNN with your internal Project ID, e.g. 1234. |
company_id | BIGINT | Positive: equals visitor_id. Negative: the visitor belongs to a company (has a company_id trait) and the absolute value references companies.id. |
visit_type | VARCHAR | v for a regular visit (pageview); i for an influence touchpoint used by TV attribution. |
user_id | BIGINT | References events.user_id and users.id. Can be NULL. |
original_created_at | TIMESTAMP | Matches visitors.original_created_at: the createdAt trait, if it was passed to identify(). Can be NULL. |
path | VARCHAR | Matches events.uri_path, except that NULL stands for no path or /. |
Most columns in visits are redundant; they are there to make complex queries cheaper. You can load only the two that matter, id and filter, and get the rest by joining events and the other tables.
Visit costs
The table is named visits_1234_costs for internal project ID 1234. It spreads each filter's daily spend over the visits of that day, which is how the dashboard arrives at a cost per visit. Like visits, it is rebuilt and loaded in full on every run.
| Column Name | Type | Description |
|---|---|---|
cpv | FLOAT | Cost per visit: amount divided by visit_count. |
visit_count | INTEGER | Number of visits the filter had on the date. |
visit_date | DATE | The date. |
filter | BIGINT | References xNNNN_filters.id where type = 'filter'. |
amount | INTEGER | Spend for the filter on the date, in cents, from amounts. |
Filters
The filters table is named after our internal ID for your project: if that ID is 1234, the table is x1234_filters_v2. It contains everything you see as filters and channels on the dashboard.
The dashboard is a tree, the "filter tree". The filters table holds both channels (type = 'group') and filters (type = 'filter'), flattened, because trees are awkward in SQL.
When joining this table to visits, join only rows WHERE "type" = 'filter'. That gives filter-level reporting; for channel-level reporting, sum the filter metrics by channel, grouping on top_parent_id, parent_id or channel_N_id.
Important notesThis table is NOT exported incrementally: filters are added, changed and removed often, by integrations and by your marketing team, so truncate it and load it again on every run.
The primary key is the composite
(id, type): two rows can share anidwithout being duplicates.Groups you create on the dashboard, such as Paid Traffic, are not in this table.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | ID of filter or channel. Not unique. |
name | VARCHAR | Name of the filter or channel. |
type | VARCHAR | Could be filter (Filter) or group (Channel). |
label | VARCHAR | A qualifier set by Attribution or an integration that says what the row is about. Can be NULL. |
integration | VARCHAR | Technical identifier of the integration, e.g. bing for Microsoft Advertising. |
parent_id | BIGINT | References id where type is group: the parent channel of this row. |
top_parent_id | BIGINT | References id where type is group: the top-level channel of this row. |
ordinal | INTEGER | Position of the row inside its parent channel. |
level | INTEGER | Nesting distance from the root level. |
sort_index | INTEGER | Position of the row in the whole tree. ORDER BY sort_index gives the dashboard's order. |
path | VARCHAR | JSON array of the channel names from the top of the tree down to this row. |
channel_N_name | VARCHAR | Name of the channel at level N of the tree above this row. |
channel_N_id | BIGINT | ID of the channel at level N of the tree above this row. |
path_level_N | VARCHAR | The channel names down to level N, joined by >>. Does not include the row's own name. |
channel_N_name,channel_N_idandpath_level_Nexist for levels 1 to 5 of the tree. If your tree is deeper than five levels, use thepathcolumn, which holds the full hierarchy.
To see the dashboard's tree from the exported filters table:
SELECT
    repeat('▷ ', level) || name,
    *
FROM
    xNNN_filters_v2
ORDER BY
    sort_index;
Filters (legacy, pre-2024)
New exports use the format above. Projects whose export was set up before 2024 receive this legacy format.
The legacy table is named x1234_filters for internal project ID 1234, and holds the same channels and filters.
The dashboard is a tree, the "filter tree". The filters table holds both channels (type = 'group') and filters (type = 'filter'), flattened, because trees are awkward in SQL.
Join it to visits on rows WHERE "type" = 'filter' only, and group on top_parent_group_id or parent_group_id for channel-level reporting.
Important notesLike the current format, this table is truncated and loaded in full on every run, and its primary key is the composite
(id, type). The dashboard's order is not preserved in the legacy format.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | ID of the filter or channel. Not unique. |
parent_group_id | BIGINT | References id where type is group: the parent channel of this row. |
top_parent_group_id | BIGINT | References id where type is group: the top-level channel of this row. |
type | VARCHAR | Could be filter (Filter) or group (Channel). |
name | VARCHAR | Name of the filter or channel. |
label | VARCHAR | A qualifier set by Attribution or an integration that says what the row is about. Can be NULL. |
integration | VARCHAR | Technical identifier of the integration, e.g. bing for Microsoft Advertising. |
path | VARCHAR | JSON array of the channel names from the top of the tree down to this row. |
Visitors
A row is added every time a new visitor is tracked or identified, so the table holds both anonymous and identified visitors.
When an anonymous visitor later identifies, Attribution keeps two rows: the anonymous visitor, and the visitor it was migrated_to. The userId you pass to identify() is not in this table; it is in users. Projects on split identity mode lay these rows out differently; see Classic vs Split Mode Identity.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. Primary key, referenced from other tables. |
user_id | BIGINT | References users.id. |
browser_id | BIGINT | References browsers.id. |
project_id | BIGINT | Internal ID of your project. |
updated_at | TIMESTAMP | When the visitor was last updated. |
ip | VARCHAR | Visitor IP address. |
traits | VARCHAR | JSON hash of visitor traits. |
email | VARCHAR | Email extracted from traits. |
company_id | BIGINT | References companies.id: the company the visitor belongs to. |
migrated_to | BIGINT | References id of the visitor this one was aliased or merged into. |
original_created_at | TIMESTAMP | When the visitor registered in your own system: the createdAt trait, extracted from traits. |
Users
The identifier column is the userId you pass in identify() and track() calls: the users your tracking identified, whether through Segment, Shopify, Heap or the snippet.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. Primary key, referenced from other tables. |
identifier | VARCHAR | The userId you passed in identify() or track(): your own user ID. |
created_at | TIMESTAMP | When the user was first written to the Attribution database. |
project_id | BIGINT | Internal ID of your project. |
updated_at | TIMESTAMP | When the user was last updated. |
original_created_at | TIMESTAMP | DEPRECATED. Use visitors.original_created_at instead. |
Amounts
Spend, from the ad integrations and entered by hand. One row is the spend for one filter on one date. This is the Spend column of the dashboard.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. The primary key for this table. |
value | BIGINT | Spent amount in cents. |
created_at | TIMESTAMP | When the amount was first written to the Attribution database. |
filter_id | BIGINT | References visits.filter, and xNNNN_filters.id where type = 'filter'. |
source | VARCHAR | Integration name, if the amount was pulled automatically. |
date | DATE | Date the spend is for. |
updated_at | TIMESTAMP | When the amount was last updated. |
project_id | BIGINT | Internal ID of your project. |
amount_range_id | BIGINT | Internal use. References the amount range this spend is part of, if any. |
deleted | BOOLEAN | Whether the spend was deleted. Always add deleted = FALSE when you query or join this table. |
original_value | BIGINT | The original value in cents, if currency conversion was applied. |
original_currency | VARCHAR | ISO code of the original currency, if currency conversion was applied. |
conversion_rate | DECIMAL(18, 6) | Conversion rate applied. |
currency_converted_at | TIMESTAMP | When the currency was converted. |
Impressions
Ad impressions and clicks reported by the ad integrations, one row per filter per date. Like amounts, this table is merged incrementally.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. The primary key for this table. |
value | BIGINT | Number of impressions. |
filter_id | BIGINT | References visits.filter, and xNNNN_filters.id where type = 'filter'. |
source | VARCHAR | Integration the row was pulled from. |
date | DATE | Date the impressions are for. |
updated_at | TIMESTAMP | When the row was last updated. |
project_id | BIGINT | Internal ID of your project. |
deleted | BOOLEAN | Whether the row was deleted. Add deleted = FALSE when you query or join. |
clicks | BIGINT | Number of clicks. |
Params
The URL parameters of pageviews, parsed out of events.uri, one row per key and value. A pageview with the uri https://example.com/?utm_source=partner&utm_campaign=AWESOME adds two rows: utm_source = partner and utm_campaign = awesome. Keys and values are lowercased and truncated, keys to 32 characters and values to 128. For the original values use events.uri.
| Column Name | Type | Description |
|---|---|---|
key | VARCHAR | Parameter key. |
value | VARCHAR | Parameter value. |
project_id | BIGINT | Internal ID of your project. |
time | TIMESTAMP | When the event happened. Matches events.time. |
event_id | BIGINT | References events.id. |
updated_at | TIMESTAMP | When the parameter was last updated. |
id | BIGINT | Unique ID. The primary key for this table. |
Properties
The properties passed with track() calls, one row per key and value. track('Custom Event', { plan: 'Starter', revenue: '$50.00' }) adds one row to events and two rows here: plan = Starter and revenue = $50.00. Keys and values are stored as passed, with no transformation.
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. The primary key for this table. |
key | VARCHAR | Property key. |
value | VARCHAR | Property value. |
project_id | BIGINT | Internal ID of your project. |
event_id | BIGINT | References events.id. |
updated_at | TIMESTAMP | When the property was last updated. |
Companies
The companies visitors belong to. A visitor is assigned to a company by the company_id and company_name traits passed to identify().
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. The primary key for this table. |
project_id | BIGINT | Internal ID of your project. |
identifier | VARCHAR | The company_id trait you passed to identify(): your own company ID. |
updated_at | TIMESTAMP | When the company was last updated. |
name | VARCHAR | The company_name trait passed to identify(). |
traits | VARCHAR | JSON hash of company traits. |
Browsers
The visitor's browser (user_agent) and anonymous ID (cookie_id). On a visitor's first pageview the snippet generates a unique anonymous ID, stores it in the browser and sends it with every call, page(), identify(), track() and alias().
| Column Name | Type | Description |
|---|---|---|
id | BIGINT | Unique ID. The primary key for this table. |
cookie_id | VARCHAR | The anonymous ID: the value the snippet stores in the browser under the _attrb key. Attribution.user().anonymousId() returns it in JavaScript. |
created_at | TIMESTAMP | When the browser was first written to the Attribution database. |
user_agent | VARCHAR | The browser's User-Agent header, for detecting platform and device. |
updated_at | TIMESTAMP | When the browser was last updated. |
project_id | BIGINT | Internal ID of your project. |
If you have any questions, write to [email protected].
Updated 1 day ago